An agency analyst receives two audits of the same client page. One report says the content is accessible, while the other flags a failure and assigns a much lower score. The account team wants a clear recommendation before a developer spends time investigating the wrong system.
A GEO checker disagreement is a diagnostic problem with several possible explanations. The reports may refer to different page versions, different processing stages, or different definitions of success. The useful response is to isolate the disputed claim and find evidence that can resolve it. Choosing the more reassuring score leaves the underlying uncertainty untouched and makes the next client conversation harder.
A GEO Checker Disagreement Starts With Scope
Write the claim in plain language before comparing totals. “The warranty paragraph wasn’t present in the retrieved content” is testable. “The page is less AI-ready” is too broad to investigate without its underlying checks.
Next, compare the target records. Capture the submitted URL, final URL, collection time, environment, and test type. Redirects, regional variants, or a trailing path difference can mean that two reports never inspected the same page state.
A matching domain is only a starting point. Check whether each result covers one page, an aggregated domain view, or a group of monitored answers. Different scopes can produce different conclusions without either report being internally inconsistent.
Use a small dispute record with an owner and a question to resolve. Include both original observations, rather than replacing the earlier one with the latest result. This preserves the sequence of evidence and makes later retesting meaningful.
The goal is agreement about the observation, not agreement between numbers.
Compare the Indexed Page With the Live Test
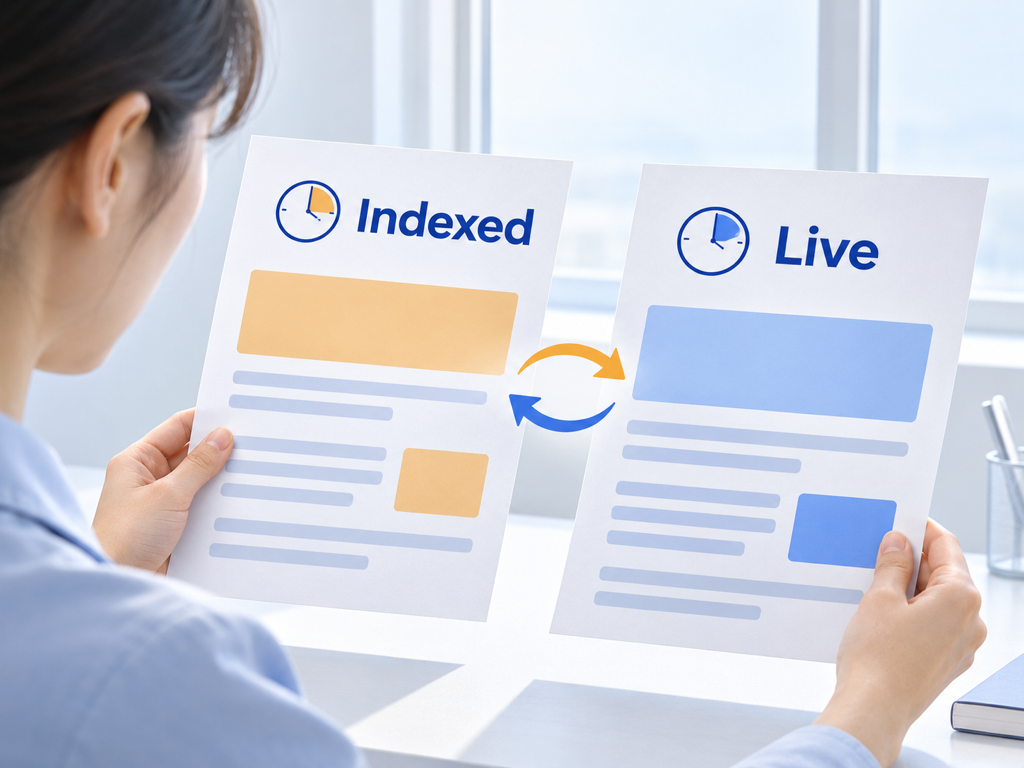
Index data and live observations answer different time-based questions. Google’s URL Inspection documentation explains that indexed information reflects Google’s stored version, while a live test examines the current page. A recent correction may therefore be visible in one result and absent from the other.
Record the relevant timestamps instead of calling this an accuracy contest. Ask when the site changed, when each report collected evidence, and which version the report describes. A current browser view doesn’t establish what an earlier collection received.
For a hypothetical example, suppose a product’s support section was repaired on Tuesday. Monday’s indexed evidence and Wednesday’s live inspection can both be correct observations. The unresolved question is whether the corrected content has been processed for the relevant search experience.
Keep canonical information separate as well. A live test cannot predict every indexing decision. Avoid converting a successful fetch into a claim that the inspected URL is the version Google selected or that it will appear in results.
Inspect Raw and Rendered Content Separately
A page can supply different useful evidence at different processing stages. The initial response may contain a shell, while later rendering populates product specifications or instructions. The question is which stage each diagnostic actually examined.
Google’s JavaScript SEO basics describe its rendering process. That documentation supports investigation of Google-visible content; it doesn’t establish that every AI search system executes the same scripts or follows the same timing.
Inspect the disputed fact, rather than relying on a screenshot of the whole page. Find whether the exact specification, condition, or instruction is present in the initial response and the rendered result. Record resource failures or access restrictions that could explain the difference.
A visible element can also be irrelevant to the tested claim. A decorative image may render correctly while its associated text is missing. Conversely, a page can contain the necessary text without reproducing every visual detail in an automated screenshot.
Keep the processing stage in the result label. “Present in rendered HTML” and “present in initial HTML” are useful findings. Combining them into a generic content-present field discards the information needed to reproduce the discrepancy.
Normalize Findings Before Comparing Scores
Map both reports to a shared evidence vocabulary. Use a small set of factual fields such as target URL, observed state, checked content, processing stage, and supporting artifact. Preserve the vendor’s original wording beside the normalized finding.
Do not manufacture equivalence between different scales. A score out of one hundred can summarize different checks, weights, and missing-data rules. Without a shared definition, averaging two scores creates a third number with no defensible interpretation.
| Disputed observation | First comparison to make | Evidence that helps | Conclusion to avoid |
|---|---|---|---|
| Content missing in one report | Initial versus rendered stage | Exact paragraph in each artifact | Every AI system misses it |
| Access passes only once | Collection time and request context | Recorded response or test result | A successful browser visit proves crawler access |
| Different total scores | Covered checks and weighting disclosure | Individual findings | The average is the true score |
| Current page differs from index | Version and collection date | Indexed and live records | The repair has already affected search selection |
Treat unknown as a valid state. A report that doesn’t expose its processing stage cannot be confidently assigned to one. The appropriate next step may be a narrower direct test or a request for clarification from the provider.
This evidence-first comparison also reduces client friction. You can explain which claims are confirmed, which differ because of scope, and which remain unresolved. That is a more actionable deliverable than declaring a winner among opaque totals.
Retest the Smallest Disputed Claim
Choose one disputed fact and define a repeatable test. Specify the URL, expected content, relevant state, collection time, and pass condition. Keep the test narrow enough that a reviewer can understand what changed between attempts.
For example, test whether a particular compatibility sentence appears in the relevant output. Avoid changing the URL, waiting for a new deployment, and altering the inspection method together. Multiple simultaneous changes can resolve the symptom while leaving its explanation uncertain.
Preserve failures as well as successes. A failed request and an empty paragraph are different observations and may need different owners. Repeated access failures can justify an infrastructure investigation; one incomplete content record may belong with the publishing team.
Google’s AI feature technical guidance is useful for checking eligibility requirements, but meeting them doesn’t guarantee selection. Limit the retest conclusion to the claim actually inspected instead of promoting a technical pass into an answer-ranking prediction.
When the dispute persists, report the unresolved boundary. Identify what evidence is unavailable, what was reproduced, and what would change the conclusion. This lets work continue on confirmed defects without treating uncertainty as a failure of the entire audit.
Use Topify Findings in an Evidence Review
Topify offers a GEO Score Checker that describes findings across access, structured data, content signals, and visibility. Enter the page being disputed and save the returned findings with its URL and collection date. Compare the individual observation with the other report before comparing the overall score, because the useful input to an investigation is the specific claim.
For questions about the answer layer, AI Search Analytics provides visibility and citation context. Use that context to decide whether a technical discrepancy deserves a separate answer review. The reconciliation sheet proposed here remains a manual evidence workflow; the public product pages don’t establish common scoring weights with another vendor or automatic resolution of conflicting diagnostics.
The immediate output should be a short decision record: confirmed issue, scope difference, timing difference, or unresolved evidence. Assign a next action only where the record supports it. A developer needs the failing condition and expected behavior, rather than a request to increase an unexplained total.
Run a Free GEO Audit in 60 Seconds. Here’s What the Score Means provides background on reading a first audit. Use that context while keeping this dispute focused on the underlying observation and its evidence.
Conclusion
Conflicting audits become easier to handle when the team compares claims before scores. Align the URL, collection time, page version, and processing stage, then inspect the smallest fact that could explain the disagreement. Keep unknown fields visible and preserve both original reports so the final decision remains traceable.
Choose one disputed page and pair a current GEO checker inspection with the evidence already available. Record what each result proves, what it leaves open, and who owns the next test. The practical outcome is a resolved claim or a clearly bounded uncertainty, followed by a separate assessment of search and answer performance once comparable observations exist.
FAQ
Which score should I trust when two tools disagree?
Start with the underlying findings. A score is only interpretable within its own scope and definition, so resolve the disputed observation before choosing an operational action.
Why can a live test differ from indexed information?
They can describe different page versions. Check the collection and deployment dates, and preserve the distinction between current accessibility and stored index evidence.
Can I average different GEO scores?
Only if their definitions and scales support that operation. Without comparable checks, weights, and missing-data rules, the resulting average has no established meaning.
Does a successful retest mean search results will change immediately?
No. It confirms the inspected condition at that time. Processing, indexing, and answer selection are separate steps that need their own observations.