A product marketing manager sees a rival recommended for a broad category question and starts drafting a competitive response. The sales team points out that the actual buyer needs a particular integration and a supported operating region. Those conditions never appeared in the monitored question.
AI search competitor analysis becomes more useful when it tests the decision the buyer actually faces. A brand can appear frequently in generic answers while being unsuitable for a constrained purchase. The task is to preserve the buyer’s requirements, verify the relevant product facts, and examine whether the recommended shortlist still makes sense when one condition changes. That produces a clearer evidence backlog than another undifferentiated visibility ranking.
Start AI Search Competitor Analysis With a Buyer Decision
Choose one decision before choosing competitors. “Select a scheduling system for a distributed support team” defines a task more clearly than “find the best software.” Record who is deciding, what they need to accomplish, and which conditions could disqualify a candidate.
Separate hard constraints from preferences. A required integration may be a qualification condition; a preferred interface style may be a trade-off. Treating both as mandatory can make the test artificially narrow, while ignoring the first can make the shortlist commercially irrelevant.
Google describes query fan-out in its AI search features. This provides context for why complex questions can involve multiple evidence needs. It doesn’t prove which searches a particular monitored answer performed or why a specific brand appeared.
Write a decision statement that a reviewer can challenge. Include the requirement’s source, such as an approved buyer brief, without exposing private customer information in public examples. Use invented organizations when illustrating the method.
Build a Constraint Ledger From Verified Facts
Create a separate record for each constraint and candidate. Include the requirement, evidence needed, current evidence location, date checked, and status. The status should allow satisfied, not satisfied, and unknown.
Unknown is essential. A product page that doesn’t mention an integration doesn’t prove that the integration is unavailable. Equally, a vague claim of broad compatibility doesn’t establish that the buyer’s exact workflow is supported.
For a hypothetical comparison between fictional products Cedar and Harbor, the ledger might ask whether a named export format is available on the relevant plan. The example supplies a test condition, not a factual claim about a real vendor. An actual review would need the vendor’s current documentation or a verified product response.
Price and availability need a scope as well. Record the relevant plan, geography, billing basis, or product version where those conditions affect the answer. A true statement about another plan doesn’t establish eligibility for this buyer.
Don’t turn the ledger into a general product review. Collect the evidence that can change this decision, and flag gaps for the appropriate owner. That keeps the test focused and reduces the chance that obsolete competitive notes will be treated as current facts.
Change One Constraint at a Time
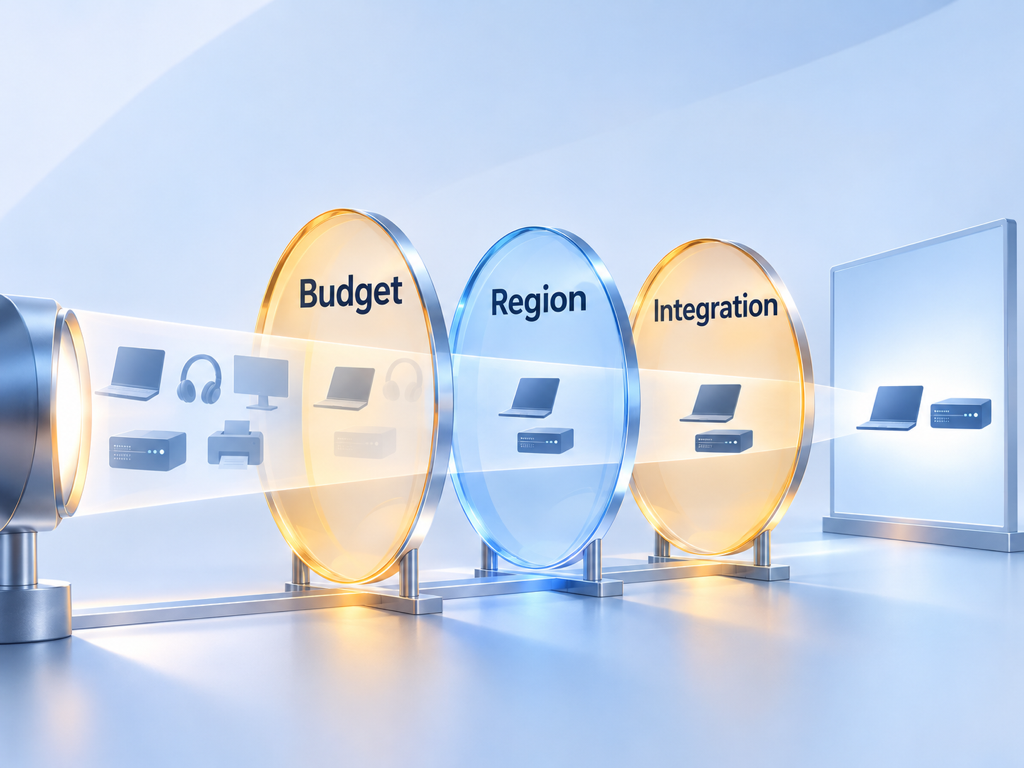
Build a base prompt that expresses the decision clearly. Create a matched variant by adding or changing one relevant requirement while preserving the rest. The purpose is to make the observed difference interpretable.
For example, compare a fictional team’s general scheduling question with the same question requiring a particular export format. Keep the buyer role, platform, collection settings, and other conditions recorded. Introducing a new budget, region, and integration simultaneously makes it harder to understand which condition mattered.
Store the original text for both prompts. A normalized label helps organize the results, but it cannot substitute for the exact wording needed to reproduce the comparison. Pair the observations so missing or invalid results don’t quietly become competitive losses.
Repeat where the decision warrants it, while describing the scope honestly. A small set of observations can reveal examples worth investigating; it doesn’t establish a population-wide preference rate. Predetermine how the team will handle an inconclusive comparison.
The method tests sensitivity to a condition. It doesn’t prove that the condition caused the model’s internal reasoning, even when the answer explicitly discusses it. Inspect the explanation and evidence before drawing a narrower operational conclusion.
Score Shortlist Eligibility Separately From Visibility
Keep two questions in different fields: did the brand appear, and does the recommendation satisfy the stated requirement? That prevents a visible but unsuitable option from being counted as a clear commercial win.
A useful coding sheet can be simple. Preserve the answer sentence, relevant condition, qualification evidence, and review status. Avoid collapsing everything into a weighted score unless the weights support a real decision and are disclosed.
| Observation | Visibility status | Eligibility status | Appropriate next action |
|---|---|---|---|
| Brand appears and verified condition is satisfied | Present | Supported fit | Review the remaining buying criteria |
| Brand appears but verified condition is not satisfied | Present | Contradicted fit | Inspect the claim and cited evidence |
| Brand appears but qualification evidence is missing | Present | Unknown | Verify the product fact |
| Brand is absent despite verified qualification | Absent | Potentially eligible | Investigate discovery and evidence coverage |
| Answer or collection fails | Unavailable | Not assessed | Resolve the observation failure |
This table is an editorial review method, not an industry scoring standard. Its value is the separation of states and the action each state supports. A team can adapt the labels while preserving that logic.
A shortlist is only useful relative to the buyer’s conditions.
Investigate Reversals Without Inventing Causes
A reversal occurs when the recommended set or ordering changes between matched observations. Start by confirming the prompts and collection conditions. Then examine whether the answer discusses the changed requirement and whether its cited evidence supports the relevant claim.
There are several possible operational findings. The model may cite an outdated product document, the available evidence may omit a qualification, or the answer may simply remain ambiguous. The observation alone doesn’t identify the internal cause.
Create a task that matches the evidence. An outdated owned fact can justify a content correction. A competitor’s apparently unsupported qualification needs verification before a competitive claim is made. An unexplained reversal may justify another controlled observation rather than immediate publishing.
Keep alternative explanations visible in the review record. A platform update, different retrieval result, or ordinary response variation can coincide with the changed constraint. Don’t turn a comparison into a causal study merely because it has two rows.
The related AI Prompt Clustering: How to Group Buyer Questions Without Hiding Intent explains why constraints can change an editorial decision. Here, the narrower purpose is to verify whether each candidate remains suitable under a specific requirement.
A final review should also identify who can resolve each unknown. Product documentation owners can verify capabilities, while regional operations can confirm availability. Keep those responsibilities attached to the requirement so an unresolved question reaches someone with access to the right evidence.
Use Topify to Review Constraint Level Gaps
Topify describes query-level brand comparisons through Dynamic Competitor Benchmarking, including differences across prompt variations. Start with the brand, relevant competitors, and a carefully scoped buyer question. Review which brands appear in each observed answer and bring the exact result into the qualification ledger rather than accepting a category-level lead as proof of fit.
The useful output is a set of condition-specific gaps: eligible but absent, visible but contradicted, or visible with insufficient evidence. Assign verification and content work from those states. The ledger and eligibility checks described here are analyst-managed additions; the public product page doesn’t establish automatic validation of integration, compliance, contractual, or regional requirements. Verify each consequential product fact independently before using it in a competitive statement.
Keep the handoff concrete. A task should identify the buyer requirement, observed answer, relevant source, factual status, and owner. That makes the monitoring useful to product marketing and sales without encouraging them to promise capabilities the product doesn’t provide.
Conclusion
Competitive visibility becomes more decision-relevant when the buyer’s constraints travel with the result. Define the purchase task, distinguish requirements from preferences, and verify the facts that could disqualify a candidate. Then compare matched questions and preserve separate fields for presence, eligibility, and missing evidence.
Use query-level competitor benchmarking to identify observations worth reviewing, while keeping qualification checks grounded in current product evidence. Start with one important buyer condition and a small, traceable comparison. The next useful deliverable is a supported fit finding or an explicit evidence gap, followed by a specific task for the person who can resolve it.
FAQ
Which buyer constraints should be tested separately?
Test conditions that could change qualification, such as a required integration, service region, or product capability. Keep preferences distinct so the test doesn’t accidentally redefine the buyer’s task.
Does missing evidence mean a competitor is ineligible?
No. Mark the condition unknown until evidence supports a conclusion. Silence on a general marketing page is insufficient proof of absence.
Can several conditions change in one comparison?
They can, but interpretation becomes harder. A matched comparison that changes one condition is usually a clearer starting point for investigating which requirement affects the observed answer.
Does a competitor’s appearance prove it meets the requirements?
No. Presence and suitability are different fields. Inspect the recommendation, its conditions, and current product evidence before treating the result as a qualified shortlist.