A brand research lead reads an answer that praises a product’s depth but warns that a small team may struggle with setup. The monitoring score looks positive, while the sales team considers the same sentence a meaningful objection. Neither reading is necessarily careless; the reviewers may be judging different things.
AI brand intelligence needs a clear evaluation target before a sentiment score can support a decision. Tone, product suitability, attribute judgments, and factual accuracy can coexist in one passage without pointing in the same direction. The useful task is to calibrate interpretation against a documented human review process, then decide which disagreements matter enough to change reporting or trigger investigation.
AI Brand Intelligence Must Define What Sentiment Means
Start by distinguishing the labels your team actually needs. A statement can sound favorable while making an incorrect claim, or express a reasonable trade-off that matters to only one buyer segment. Calling both “sentiment” makes the score difficult to act on.
Use separate questions for tone, attribute evaluation, suitability, and factual support. Tone describes how the brand is presented; suitability asks whether it fits a particular requirement. Factual accuracy requires evidence beyond whether the language sounds positive or negative.
The research survey on inter-coder agreement examines how annotation reliability is assessed. Its practical lesson for this workflow is to define the task and examine agreement rather than assuming that a human label is self-explanatory ground truth. It does not provide a universal acceptance threshold for commercial brand sentiment.
Write the decision the label will support. A customer-support team may need explicit service complaints, while a positioning team may care about enterprise suitability. Choosing the purpose first prevents the team from tuning one score to answer several incompatible questions.
Write Labels Around Concrete Brand Attributes
Create a short codebook with examples and counterexamples. Define the passage a reviewer should score, the attribute under discussion, and whether an implied judgment is sufficient. Keep “not discussed” separate from neutral sentiment so silence doesn’t become a statement of indifference.
The following labels are a proposed editorial review scheme, not a description of a vendor’s internal classifier.
| Label | Meaning for a named attribute | Example interpretation |
|---|---|---|
| Positive | Explicit favorable assessment | Setup is described as straightforward |
| Negative | Explicit unfavorable assessment | Setup is described as difficult |
| Mixed | Material praise and criticism of the same attribute | Quick initial setup but difficult advanced configuration |
| Neutral | Attribute discussed without evaluation | Setup requires an administrator account |
| Uncertain | Meaning or entity cannot be resolved confidently | Ambiguous comparison with no clear subject |
| Not discussed | No relevant attribute statement | Answer names the brand without discussing setup |
Specify how to handle quotations, competitor comparisons, negation, and conditional language. “Not suitable for a solo operator” is different from “not suitable,” and removing the condition changes the business meaning. Reviewers should preserve the relevant passage rather than submitting only a label.
Keep examples compact enough to use during real review. A codebook that requires a long interpretation meeting for every row is unlikely to remain consistent under weekly reporting pressure. Add complexity when a recurring failure justifies it.
Blind Review a Stratified Sample
Select examples across the dimensions that could change interpretation. Include different platforms, attributes, languages where relevant, and both favorable and unfavorable wording. Don’t judge performance from a convenient collection of easy positive answers.
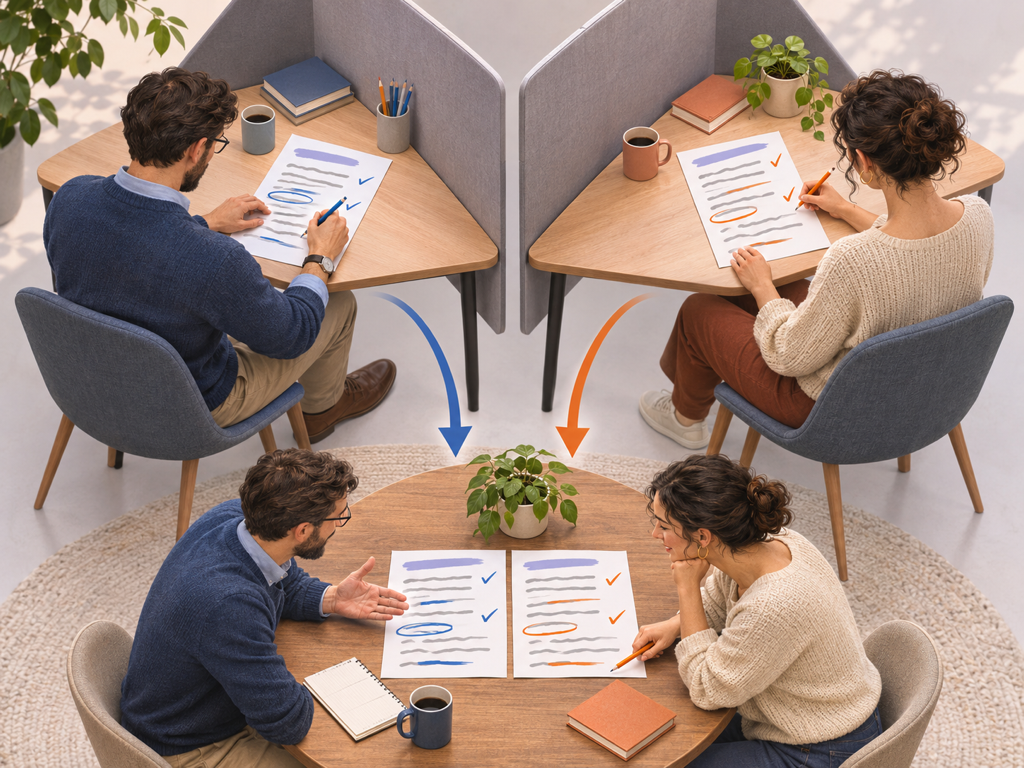
Have reviewers label the same passages independently before seeing one another’s decisions. When possible, hide the automated score during this first pass. Otherwise, the score itself may anchor the human judgment you intended to use as an independent check.
Preserve the full answer as context while identifying the exact span being scored. A sentence can reverse or qualify an earlier statement, and a detached fragment can make an otherwise reasonable label look wrong. Record when the context still leaves the subject or meaning unclear.
Use a pilot sample sized to your team’s capacity and the decision’s consequences. There is no single number that makes every sentiment audit reliable. Report the composition and size of the reviewed sample so readers can judge which types of language it actually covered.
Diagnose Disagreement Before Tuning a Score
Inspect disagreements before treating them as classifier errors. Two reviewers may disagree because the codebook is unclear, the passage is ambiguous, or one reviewer missed a condition. A model-to-human mismatch has a different meaning when humans disagree with each other.
Use a confusion table to find patterns rather than only an overall agreement percentage. Repeated confusion between neutral and positive may indicate that factual product descriptions are being mistaken for praise. Frequent mixed-versus-negative disagreements may show that the unit being scored is too broad.
Agreement isn’t the same as correctness.
For a hypothetical exercise, two reviewers agree on eighteen of twenty passages, giving 90 percent raw agreement. That figure alone doesn’t show whether rare negative cases were handled well, whether the labels are heavily imbalanced, or whether both reviewers shared the same mistaken interpretation. Review those conditions before using the number as a quality claim.
Resolve disputes through a documented adjudication step. Preserve initial labels, the final decision, and the reason for the change. If a rule is revised, test earlier difficult cases again rather than quietly editing the answers that made the old rule look inconsistent.
Keep Calibration Results Separate From Brand Trends
A revised labeling rule can move a sentiment trend without any change in the underlying answers. Preserve the classifier or codebook version with each interpretation. Where feasible, compare old and new rules on the same fixed set of passages before presenting a historical change.
Keep calibration results in their own report. Its questions concern agreement, error types, and coverage of the reviewed sample. The brand trend report concerns observed representation over time, and should disclose when measurement rules changed enough to affect comparison.
A practical action queue can distinguish a misleading statement, a genuine product trade-off, and a scoring problem. Only the first necessarily suggests a factual correction. A well-supported objection may call for better buyer guidance rather than a campaign to remove negative language.
The wider brand intelligence playbook discusses how representation informs brand work. Calibration supplies a quality control for that interpretation, especially when a single favorable score hides an objection that matters to a particular audience.
Review errors in the context of the action they might trigger. Misclassifying an incidental compliment may have little consequence, while missing a repeated suitability objection can misdirect a campaign. A review policy can prioritize the latter without claiming that every label deserves the same operational response.
Preserve uncertain passages as useful examples. Removing them from the working codebook makes the process appear cleaner while leaving future reviewers exposed to the same ambiguity. A compact library of resolved and unresolved cases can improve consistency without pretending that language always has one obvious interpretation.
A useful calibration record explains disagreement instead of merely removing it.
Use Topify to Find Answers Worth Reviewing
Topify can serve as the observation and prioritization layer for this process. Its brand monitoring feature describes sentiment trends and the language used about a brand. Start with a defined brand and relevant evaluation prompts, then inspect answers associated with a meaningful change or recurring objection. The review output should connect a passage, an attribute, and a proposed next action, making it easier to distinguish a representation issue from a classification disagreement.
Keep the human calibration process explicit and independent. This method doesn’t assume that your account can retrain a classifier, change its thresholds, or replace native scoring rules. Preserve your codebook, blind labels, and adjudication decisions in a separate review record unless a supported product workflow provides them. Use the platform score to help select cases, then evaluate the underlying language before assigning content work or claiming that brand perception improved.
Conclusion
A sentiment score becomes more useful when the team knows which judgment it represents. Define the attributes and labels, review a varied sample independently, and investigate disagreement before adjusting reports. Preserve measurement versions so a rule change doesn’t masquerade as a change in brand reputation.
Begin with one recurring business concern, such as setup difficulty or suitability for a buyer segment. Review a manageable sample, retain the original passages, and document the decisions that resolve ambiguous cases. Use Topify’s brand monitoring workflow to identify relevant answers and track subsequent observations. The immediate objective is a clearer action decision, not a more flattering score that has lost the trade-offs your buyers need to understand.
FAQ
Why can humans disagree with an AI sentiment score?
They may be judging different attributes, reading conditions differently, or using an unclear label definition. Inspect the passage and the evaluation task before identifying the cause.
Should mixed sentiment be forced into positive or negative?
Not automatically. A mixed label or attribute-level assessment can preserve information that a single polarity would hide. Choose the method that supports the intended decision.
Is raw agreement enough to validate sentiment labels?
No. Inspect label distribution, difficult cases, reviewer consistency, and the consequences of errors. A high overall percentage can coexist with poor handling of rare but important cases.
Can this process change a platform’s sentiment model?
Only if the platform offers a supported mechanism for doing so. The workflow remains useful as an external review and interpretation process even when native scores cannot be customized.