A marketing operations lead approves a monitoring platform after a persuasive demo. Three months later, the team needs to move its records into a warehouse, and the export contains weekly scores without the answers, source links, or configuration needed to explain them. The charts traveled; the evidence didn’t.
Search intelligence solutions should be evaluated on what a team can reconstruct outside the interface. A downloadable file is a starting point, but portability also depends on record identity, field meaning, relationships, and the ability to distinguish an original observation from a later interpretation. Before committing a reporting workflow to a vendor, decide which decisions must remain explainable after the dashboard is gone.
Search Intelligence Solutions Need a Portable Evidence Record
Portability starts with a reporting question rather than a file format. Ask whether a reviewer could reproduce one reported result, explain its denominator, and inspect the observations behind it using the delivered records. A spreadsheet containing a score may support presentation without supporting that investigation.
The W3C provenance model connects data with the activities and agents involved in producing it. Applied to monitoring, that principle suggests preserving the answer, the collection context, and the transformation that produced a metric. It doesn’t prescribe a specific commercial export or certify a vendor.
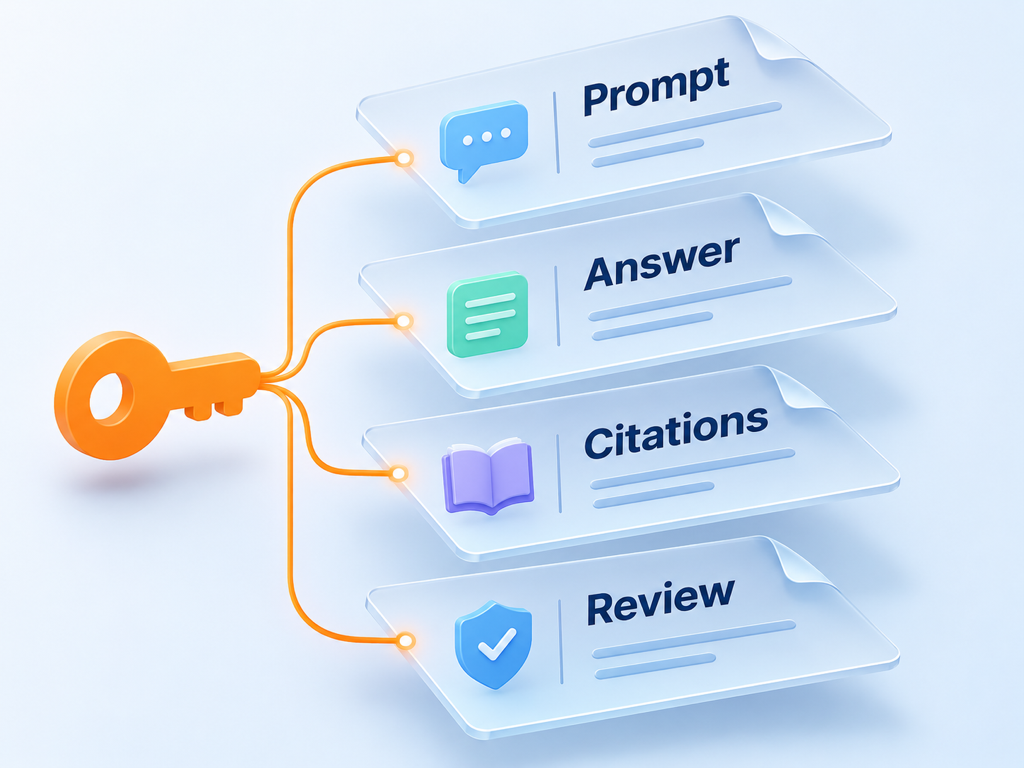
Separate three deliverables in the procurement discussion. An observation package preserves what was collected; a configuration package explains what was requested; a reporting package describes how results were calculated. Their relationships matter more than whether they arrive in one archive or several files.
A screenshot can document the interface, but it usually cannot replace those relationships. When a buyer asks why a rate changed, the team needs eligible observations and calculation rules, not just a picture of the final percentage.
Define the Minimum Record Before the Demo
Give vendors a small field contract before asking for an export. Identify which fields are essential to your use case, which are desirable, and which may legitimately be unavailable. A missing proprietary score formula has a different consequence from a missing observation timestamp.
Use a contract like the following as a proposed acceptance checklist. It is a buyer-designed standard, not a claim that every platform already provides these fields.
| Record | Minimum information | Acceptance question |
|---|---|---|
| Observation | Stable ID, collection time, platform, status | Can a retry be distinguished from the original attempt? |
| Prompt configuration | Prompt ID, exact wording, market and language | Can the team identify what was requested? |
| Answer | Original collected text or accessible evidence reference | Can a reviewer inspect the underlying response? |
| Citation | Observation ID, displayed URL, relevant location | Can several links be tied to one answer? |
| Interpretation | Label, rule or version, review status | Can a later classification be separated from the source? |
| Report | Population, exclusions, formula, reporting window | Can one published number be reconstructed? |
Document encoding, timezone, empty-value conventions, and the meaning of every status. A blank answer could mean failed collection, unavailable text, or an answer that was genuinely empty. Those states cannot safely share one undocumented cell.
Agree on delivery boundaries too. Historical access, bulk extraction, supporting images, and configuration history may have different terms or technical limits. Record the actual answer rather than treating a generic “export available” statement as evidence that all four are included.
Run a Small Export and Rebuild One Report
A limited acceptance exercise exposes structural problems without requiring a full migration. Select a reporting window, obtain its records through an authorized export method, and reproduce one modest statistic. Keep the original files unchanged and perform transformations in a separate working copy.
For an illustrative test, imagine ten eligible answers and four that mention a defined brand. The reconstruction should produce four divided by ten, or 40 percent, under the stated rule. These are demonstration numbers, not a vendor benchmark or a recommended minimum sample for measuring real visibility.
Now follow one positive observation through the delivered files. Its prompt, answer, citation rows, and labels should connect through documented identifiers. If the files only align by row order, ask what happens when one file omits an unavailable record or sorts differently.
Verify that the independent calculation and the interface use the same population. A difference may be explained by timezone, exclusions, or the treatment of retries. Resolve that explanation before concluding that the platform is wrong or that the export is unusable.
Test Missing Fields, Duplicates, and Time Boundaries
A useful export survives imperfect observations. Request a sample containing an unsuccessful collection, a retry, several citations in one answer, and a boundary crossing between reporting days. The purpose is to see whether the record structure preserves distinctions that normal summaries can hide.
Count unique observation IDs before and after joining citation rows. One answer with three links should not become three brand observations. A flat export can still be usable, but the team must know which repeated fields represent a relationship rather than additional evidence.
Check time interpretation with a specific boundary example. A record collected near midnight may belong to a different calendar day after timezone conversion. Preserve the original timestamp and its timezone, then derive the reporting date explicitly instead of overwriting the original time.
Portability fails quietly when missingness becomes an ordinary zero.
Add a simple reconciliation note to each exercise: records received, unique observations, excluded states, duplicates, and unexplained differences. Assign an owner to each unresolved issue. This creates a concrete acceptance decision rather than an argument over whose chart looks more convincing.
Keep Native Data and Derived Scores Distinct
Raw observations and derived scores serve different purposes. Original answer text lets a future reviewer apply a new classification rule; a sentiment score records one interpretation under a particular method. Losing either may be acceptable for some uses, but they should never be treated as interchangeable.
Keep a vendor-specific metric in its original field and namespace. If the team defines a separate metric, give it a separate name, denominator, and calculation version. A warehouse should not silently relabel a proprietary score as a universal measure of buyer preference.
Plan for partial portability. A platform may export answer evidence while retaining some internal ranking or enrichment logic. The buyer can still accept that arrangement if its reporting requirements are met and the limitation is documented before the dependency becomes expensive.
The broader comparison of search intelligence coverage helps frame which observation capabilities belong in a search stack. Portability adds another question: which evidence can the team retain and explain independently of that stack?
Test the receiving process as well as the file. Give an analyst who wasn’t involved in the demo the exported package and its field dictionary, then ask them to explain one result. Questions they cannot answer identify documentation gaps that a technically valid download may conceal.
Make acceptance conditions observable. A buyer can require a reconciled population and a documented explanation for excluded records without demanding access to every internal model. That distinction keeps procurement focused on operational needs rather than an impractical promise of complete transparency.
An export is useful when the next analyst can work with it.
Use Topify Within an Explicit Acceptance Checklist
Topify can be evaluated as the generated-answer observation layer within this process. Its current AI search analytics offering describes brand visibility and citation analysis. Start with a defined brand, relevant prompts, and the markets your team needs to observe, then review the resulting answers and source patterns against the decisions in your checklist. The useful output is a set of observations that helps prioritize an investigation, rather than an isolated score copied into a presentation.
Treat export completeness as a separate procurement question. Ask which original answers, citation relationships, configuration fields, and historical records your actual account can deliver, and test the supported method before building a dependency. The public feature description alone doesn’t establish that every proposed field is exportable or that a proprietary calculation can be reproduced. Keep any manual evidence log clearly separate from native product capabilities.
Conclusion
A portable monitoring system lets a team explain a result after the interface changes or the contract ends. The acceptance decision should turn on preserved observations, stable relationships, and documented calculations. A CSV button is useful, but it doesn’t establish that the evidence needed for your particular reports will survive the move.
Start with one reporting question and one small export exercise. Reconstruct the result, investigate differences, and record any accepted limitations before expanding the workflow. When assessing Topify’s AI search analytics, pair the observation use case with explicit questions about the records your account can retain. The goal is a reporting process whose meaning remains available to the people responsible for defending it.
FAQ
What makes a search intelligence export portable?
It preserves enough documented records and relationships to support the receiving team’s intended use. The required level depends on whether the team needs presentation, independent analysis, or a reproducible audit.
Does a CSV export guarantee report reproducibility?
No. The file may omit answers, identifiers, exclusions, or calculation rules. Rebuild one result from the delivered records before accepting that claim.
Must every proprietary score be reproducible?
Not necessarily. A team can retain a vendor score as a vendor-specific interpretation while calculating separate metrics from preserved observations. Document what cannot be independently recreated.
What should a small team test first?
Trace one reported result back to its prompts, eligible answers, and citations. Include a failed attempt and a retry so that the exercise tests more than an ideal record.