A content operations lead opens a review queue and sees 40 AI-assisted pages waiting for approval. The prose is fluent, the headings are clean, and every draft follows the template. Yet one title promises a feature the product does not have, two citations point to outdated documentation, and the schema describes a price that disappeared last quarter.
The failure is not that a model wrote sentences. The failure is that the review process treated readable copy as publishable evidence. A useful AI content audit must inspect the entire page system, assign ownership for consequential claims, and leave a record that improves the next production cycle.
AI Content Risk Extends Beyond the Body Copy
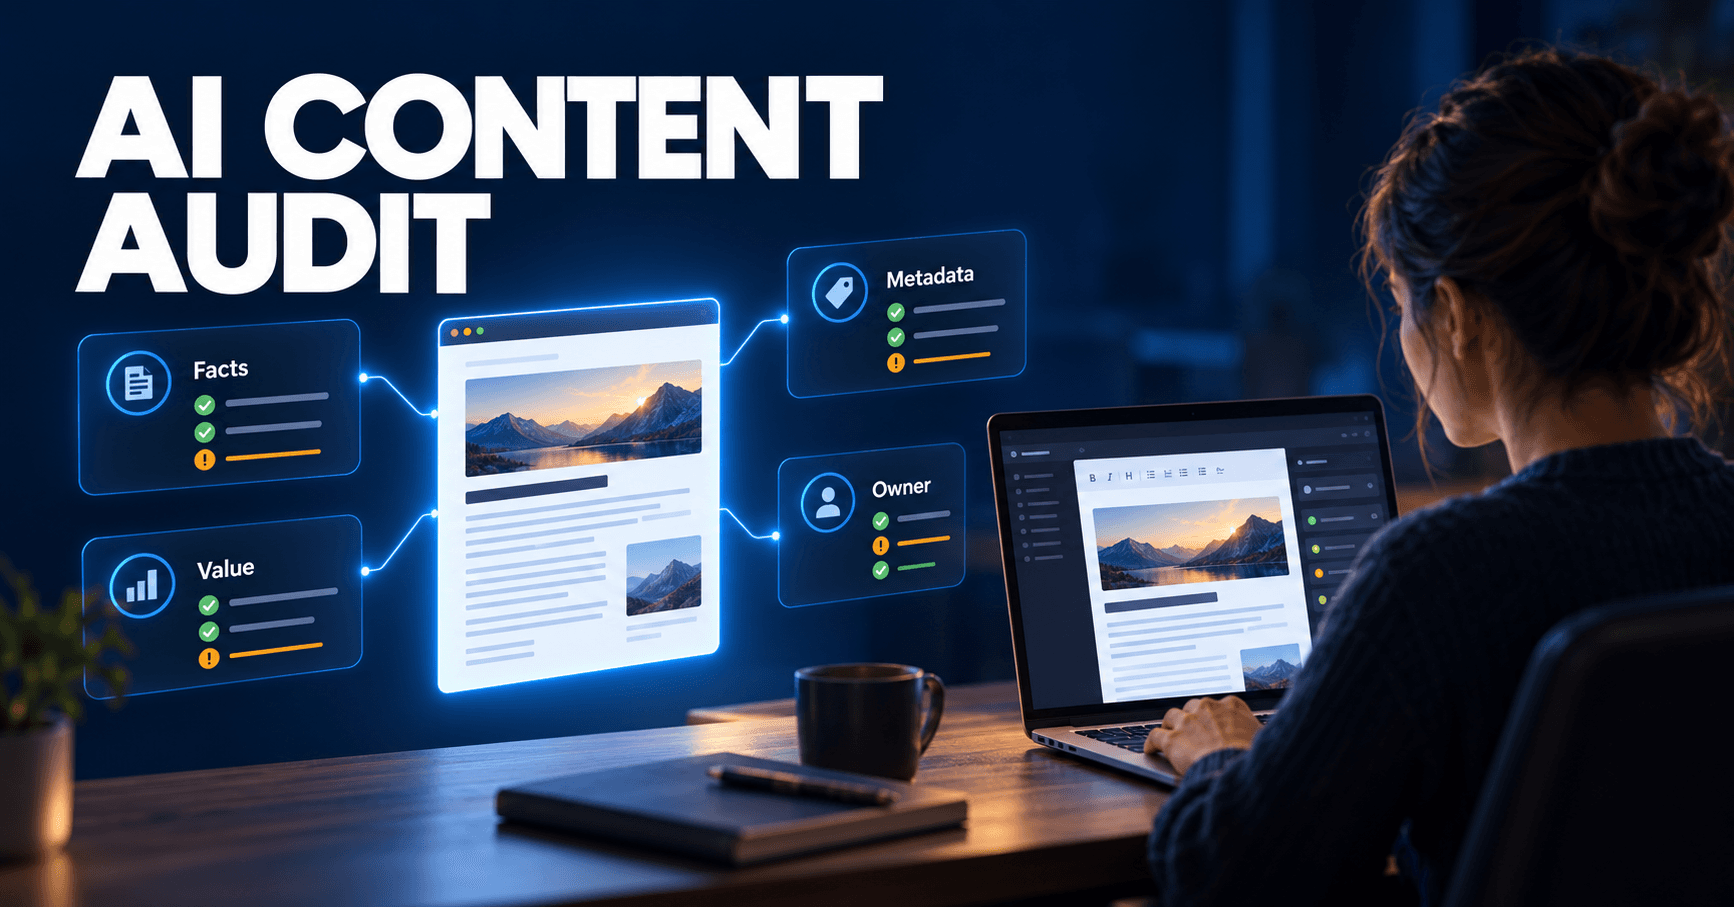
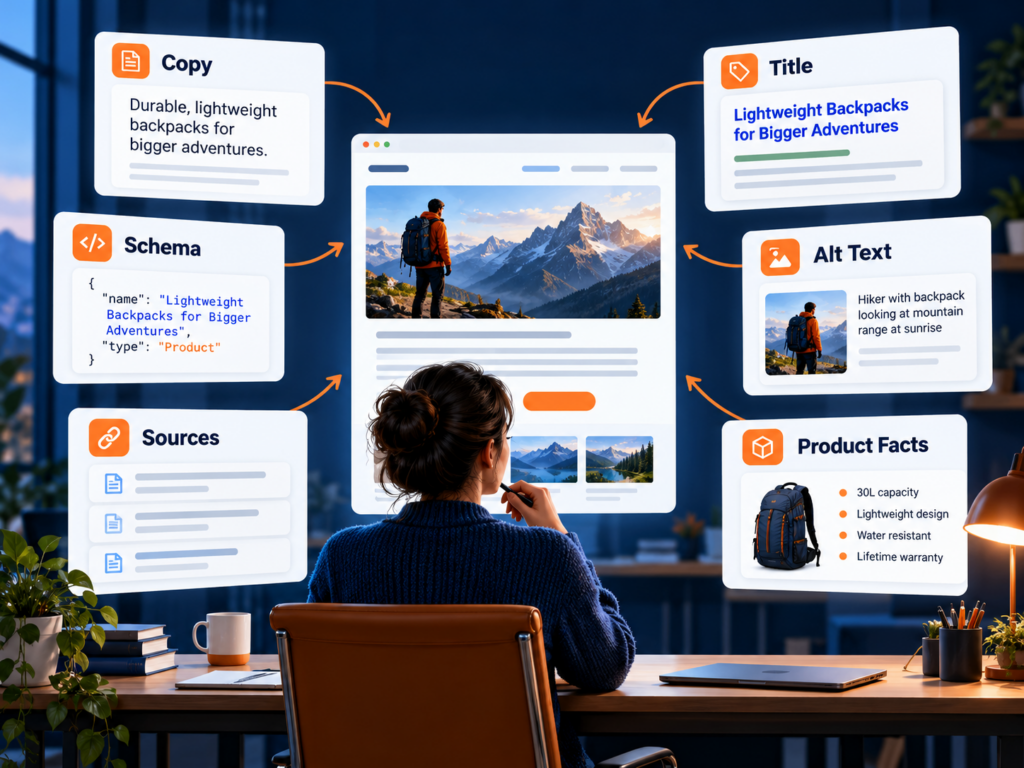
An AI-assisted page can be accurate at paragraph level and still be unsafe to publish. Titles, meta descriptions, structured data, image alt text, tables, captions, and internal links can each introduce a claim that never appears in the body.
Google’s October 2026 guidance on generative AI content makes that scope explicit. It recommends manual fact-checking and review for accuracy and trustworthiness, and says the review also applies to title elements, meta descriptions, structured data, and image alt text.
That changes the unit of review. You are not approving a document. You are approving a set of visible and machine-readable representations of the same subject.
A complete inventory should cover:
- page copy, tables, FAQs, and captions;
- title, description, canonical URL, and social preview text;
- structured data and any feed fields derived from the page;
- image content, provenance metadata, and alt text;
- source URLs, publication dates, and claim-to-source matches;
- product facts, prices, availability, and other time-sensitive details;
- internal links, calls to action, and ownership for later updates.
Separate Factual Accuracy From Original Value
Accuracy is necessary, but it is not the only pass condition. A page can repeat correct facts while adding no useful synthesis, first-hand evidence, operational detail, or decision support.
Google warns that generating many pages without adding value may fall under its scaled content abuse policy. Its updated guidance also points reviewers to the Search Quality Rater Guidelines sections covering scaled abuse and main content produced with little effort, originality, or added value. Google is careful to say that quality-rater evaluations do not directly set rankings, so treat the reference as a quality lens, not a formula for ranking first.
Run two separate tests:
- Truth test: Are claims current, specific, correctly qualified, and supported by the linked source?
- Value test: Does the page help a defined reader make a decision or complete a task better than the source material alone?
The distinction prevents a common approval error. An editor verifies every statistic, then publishes a polished summary that contributes nothing new. The page passes fact-checking but fails the reader.
Original value does not require proprietary research in every article. It can come from a useful comparison, a tested workflow, an annotated example, an implementation checklist, a transparent calculation, or a clear explanation of where official guidance stops.
Use a Four-Layer AI Content Audit
A reliable review sequence moves from evidence to meaning, then to machine-readable fields and release ownership. Each layer catches a different class of failure.
| Audit layer | Core question | Evidence to inspect | Release blocker |
|---|---|---|---|
| Claims | Is every consequential statement supported and current? | Primary sources, dates, product documentation, calculations | Unsupported fact, stale price, invented outcome |
| Reader value | Does the page resolve a concrete task or decision? | Search intent, outline promise, examples, comparison logic | Commodity summary, missing next step |
| Page system | Do copy, metadata, schema, images, and links agree? | Rendered page, source HTML, validators, link checks | Contradiction, misleading markup, broken evidence path |
| Governance | Can someone explain and maintain the decision? | Owner, review log, expiry date, correction history | No accountable owner for high-risk content |
Start with claims because weak evidence should stop the review before line editing consumes time. Mark each material claim as supported, qualified, removed, or assigned for expert confirmation.
Next, compare the finished draft with its editorial promise. The introduction should identify the reader’s real problem, and the conclusion should produce a decision or action. If the article becomes a generic overview halfway through, revision is more valuable than another grammar pass.
Then inspect the page system. Google’s general structured data guidelines require markup to represent visible page content and remain current. A syntactically valid block can still be misleading, and passing a validation tool does not guarantee a rich result.
Finally, log who approved the page, which sources establish its current state, and when the volatile facts should be reviewed again.
Match Review Depth to Page Risk
Not every page needs the same review budget. A glossary definition and a medical treatment comparison do not carry equal consequences, even when both contain AI-assisted text.
Score review depth across four dimensions:
- Decision consequence: Could an error affect health, money, legal rights, security, or a major purchase?
- Fact volatility: Can prices, limits, rules, eligibility, or product availability change quickly?
- Evidence complexity: Does the page reconcile several sources, disputed findings, or vendor claims?
- Automation scale: Will one template or prompt publish the same failure across hundreds of URLs?
Low-risk, stable pages may use a trained editor plus automated checks. High-risk pages need a qualified subject-matter reviewer who can challenge the evidence and the framing, not simply approve fluent prose.
Scale increases the risk even when each page looks ordinary. A wrong field in one article is a correction. The same wrong field propagated through a template is an incident.
Build escalation rules before the queue grows. For example, send any health or legal recommendation to a domain expert, any pricing statement to the product owner, and any generated comparison table to a reviewer who can reproduce the data.
Log Corrections So the Production System Improves
A correction that ends with the draft wastes most of its value. Every meaningful finding should update the system that produced it.
Use a compact correction log with five fields: the failure, its source, affected pages, immediate fix, and preventive change. Preventive changes might include blocking an unreliable source, adding a required evidence field, changing a prompt, adjusting a content template, or assigning a human reviewer earlier.
Group findings weekly. Repeated problems reveal whether the bottleneck sits in research, prompt design, source freshness, template logic, or final review.
Here is the practical difference: editing changes one page; governance changes the next hundred pages.
Do not use the log to score writers by raw error count. High-risk reviews naturally uncover more issues. Measure whether repeated failure types decline and whether reviewers can trace published claims to current evidence.
Monitor What Changes After Publication
Pre-publication approval cannot prove how search engines and answer systems will interpret a page. After release, monitor technical eligibility, search performance, citations, and brand descriptions as separate signals.
Search Console can reveal indexing and structured-data problems. Analytics can show qualified visits and conversions. Answer-level monitoring can show whether representative AI systems cite the page, mention the brand, or repeat outdated facts.
Topify can provide one implementation of the answer-level layer. A team can define a stable prompt set, observe mentions and cited sources, and use the Knowledge Freshness Checker to inspect whether AI systems reflect current brand events. These observations do not prove that one page caused an answer change. They help identify where a deeper source and timing investigation is worthwhile.
Keep three labels in the post-publication report:
- Observed: the page was indexed, cited, or associated with a changed description.
- Inferred: the timing and evidence suggest a relationship, but other causes remain possible.
- Unknown: the system does not expose enough information to make a defensible claim.
That vocabulary protects the audit from becoming a performance story built on coincidence.
Build a 30-Day Audit Rollout
Start with a bounded sample instead of applying a heavy process to the entire library. Select pages across risk levels, templates, authors, and content types.
During week one, define the audit rubric and train reviewers on claim mapping. During week two, audit 10 to 20 representative pages and log failure patterns. During week three, update prompts, templates, and ownership rules. During week four, run a second sample and compare repeated failure types, review time, and unresolved blockers.
Track operational metrics that improve the system:
- percentage of material claims with a current primary source;
- percentage of pages with an assigned update owner;
- repeated errors by template or prompt;
- time spent on low-risk versus high-risk review;
- number of metadata or schema contradictions found after copy approval;
- correction rate after publication.
Do not optimize the rollout around pages approved per hour. A faster queue can simply hide more defects.
Conclusion
An AI content audit succeeds when it treats a page as more than readable prose. Claims, reader value, metadata, schema, images, links, and ownership all shape what users and machines receive.
Begin with a small, mixed-risk sample. Separate factual accuracy from original value, stop unsupported claims before line editing, and route consequential pages to qualified reviewers. Then turn every correction into a prompt, template, source, or governance improvement. Measure repeated failure types rather than celebrating raw publishing speed. The immediate result is a safer release. The larger payoff is a production system that becomes easier to trust as volume grows.
FAQ
What should an AI content audit include?
It should review material claims, source freshness, original reader value, titles, descriptions, structured data, images, alt text, links, and update ownership. The exact depth should increase with consequence, volatility, evidence complexity, and publishing scale.
Does Google penalize AI-generated content?
Google does not describe AI use alone as a violation. Its guidance focuses on accuracy, quality, relevance, and added value. Generating many pages without value may violate the scaled content abuse policy.
How often should AI-generated pages be reviewed?
Set the cadence by volatility. Stable educational content may receive scheduled quarterly or annual checks, while prices, regulations, product limits, and rapidly changing platform guidance may need monthly or event-triggered review.
Who should approve AI-assisted content before publication?
A trained editor can approve low-risk material. Pages affecting health, finance, law, security, or major purchases should also receive review from a qualified subject-matter owner who can validate evidence and recommendations.