A global SEO lead runs the same translated prompt in Germany, Türkiye, South Africa, and the United States. The brand appears in one market, loses to a directory in another, and never sees the expected search feature in a third. The team concludes that the localized content failed.
That conclusion skips the product layer. Search features, eligible business models, local source pools, languages, and competitors can differ by region. Regional search optimization begins by mapping the experience that actually exists in each market. Only then can a team compare prompts, content, citations, and commercial outcomes without blaming execution for a feature that was never available.
Regional Search Optimization Starts Before the Content Gap
Visibility differences can come from several causes:
- a search or AI feature is available in one market but not another;
- the same feature supports different query types by region;
- local language changes the user’s decision, not only the wording;
- different aggregators, suppliers, publishers, and communities dominate the source pool;
- business profiles, merchant data, and local pages differ in completeness;
- legal or product rules change what the interface can show;
- the brand serves one market directly and another through partners.
Diagnose these layers before rewriting content. A localized page cannot enter a regional feature whose eligibility model excludes the business or query.
Use a gap classification: unavailable feature, ineligible business model, weak local entity data, missing intent coverage, inaccessible content, thin source presence, or underperforming content. Each category leads to a different action.
This is the core of regional search optimization: compare like with like before optimizing unlike experiences.
Map Search Experiences Before You Compare Results
Google’s regional Search experience documentation provides a current example of why the map matters. In the European Economic Area, aggregator and supplier units can apply to hotels, flights, ground transportation, products, and local businesses. Türkiye has dedicated places-site experiences for certain queries, while South Africa has badges, refinement chips, and structured-data carousel support for its own set of verticals.
Feature availability can also differ inside generative Search. Google’s AI features guidance states that AI Overviews and AI Mode use different models and techniques, and that AI Overviews appear only when Google considers them additive to classic Search.
Build a market-feature matrix before collecting visibility data.
| Market field | Question | Evidence source | Decision it supports |
|---|---|---|---|
| Region and language | Where and in which language is the query run? | Test protocol, official availability docs | Whether results are comparable |
| Available experience | Which classic, vertical, or AI feature can appear? | Official product documentation | Which surface to monitor |
| Eligible business model | Aggregator, supplier, publisher, merchant, local business? | Eligibility documentation | Whether participation work is justified |
| Query class | Product, local, travel, informational, comparison? | Search observation and intent research | Which content and data are relevant |
| Source pool | Which domains and local platforms recur? | Citation and result review | Distribution and partnership priorities |
| Measurement surface | Search Console, analytics, feed status, answer observation? | Platform reporting docs | What can be measured defensibly |
Record the date because availability changes. A comparison without an as-of date can age into misinformation.
Localize Prompts by Decision, Not Literal Translation
Literal translation preserves words while losing the buyer’s context. Product categories, regulatory terms, location patterns, currencies, and common qualifiers change the decision a prompt expresses.
Start with a shared intent framework: discover, compare, verify, locate, price, purchase, troubleshoot, or replace. Then ask a local reviewer to express how people in that market frame the decision.
For example, “best business internet provider” may require different speed units, contract terms, service areas, and evidence in each country. A direct translation can produce a grammatically correct prompt that few local buyers use.
Keep the intent stable enough for comparison but allow market-specific evidence. Track both a global cluster label and the exact local prompt.
Use local-language sources when they are authoritative. Translating an English source does not create local proof for a market-specific claim.
Benchmark Competitors Inside Each Market
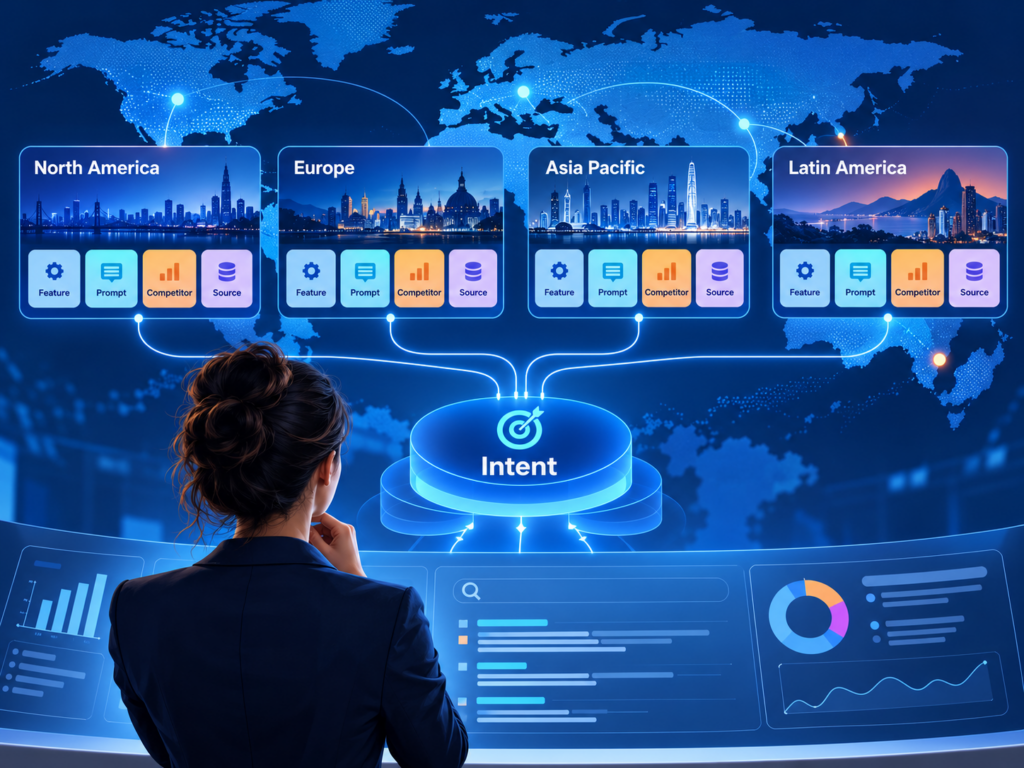
A global competitor set can obscure the companies that actually appear in local decisions. A multinational brand may compete with regional marketplaces, publishers, directories, resellers, or public institutions in different countries.
Build a market-level competitor set from observed answers and search results, then classify each entity:
- direct product or service competitor;
- aggregator or comparison service;
- publisher or review source;
- distributor or local partner;
- community or social platform;
- government or standards authority.
This classification prevents a source from being mistaken for a commercial rival. A directory can dominate citations without selling the same service.
Compare visibility, position, sentiment, and citation sources within the same market, language, prompt cluster, and date range. Do not average markets before diagnosing them.
An overall global score can be useful for executives, but action planning needs the segmented evidence underneath it.
Audit Local Entity and Commerce Data
Regional discovery depends on facts that ordinary editorial content may not control. Business Profile details, Merchant Center feeds, availability, local landing pages, organization information, and partner data can each shape the result.
Check names, addresses, service areas, currencies, language variants, prices, inventory, return terms, contact paths, and current product categories. Ensure structured data matches the visible page and that the preferred canonical URL is accessible.
Google’s AI features guidance says there is no special AI schema or machine-readable file required for AI Overviews or AI Mode. It recommends established SEO practices, including crawl access, internal links, textual content, useful images and videos, accurate structured data, and current Merchant Center and Business Profile information.
Do not create llms.txt and consider the regional work complete. Google has stated that it is not needed for Google Search and does not positively or negatively affect Search visibility.
Create one local source of truth for commercial facts, then distribute those facts to pages, feeds, profiles, and partner systems. Translation should consume that source rather than inventing a local value.
Use Multi-Country Monitoring to Find the Real Cause
Regional monitoring should hold some variables stable and segment others deliberately. Use the same intent cluster, a documented prompt protocol, local language, fixed observation dates, and market-specific competitor sets.
Topify positions its platform around visibility, sentiment, position, prompt discovery, competitor benchmarking, and citation-source analysis. A global team can use that type of workflow to compare representative prompts by country while retaining the exact answers and cited sources for diagnosis.
Pair answer monitoring with first-party systems. Search Console, analytics, commerce data, feed status, and lead quality answer different questions. AI answer visibility can change without referral traffic, and traffic can change because of seasonality or paid activity.
When a gap appears, follow the evidence chain:
- Was the feature available and triggered?
- Was the business and content eligible?
- Did the localized prompt represent real intent?
- Which sources and competitors appeared?
- Were local facts accurate and crawlable?
- Did the user outcome change?
This sequence prevents a team from rewriting a page when the real problem is feed eligibility or a missing local profile.
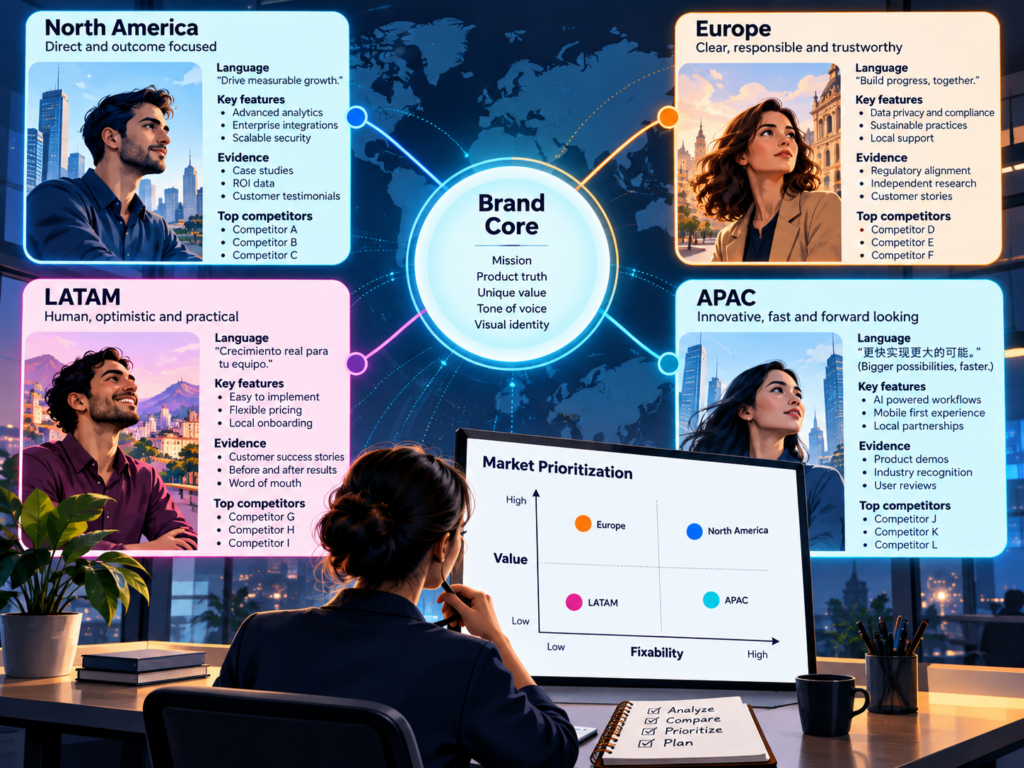
Prioritize Markets by Fixability and Business Value
Not every gap deserves immediate work. Score opportunities on business value, feature relevance, technical readiness, evidence gap, effort, and confidence.
Prioritize a market when the feature supports the category, the brand serves the users, source data is trustworthy, and a fix can change a meaningful decision. Defer when availability is uncertain, the product is not sold locally, or the required business model does not match.
Separate three action types:
- Technical: crawl access, canonicalization, structured data, feeds, or profile accuracy.
- Content: missing local evidence, weak comparison, untranslated decision detail, or stale facts.
- Distribution: absence from locally cited publications, directories, communities, and partners.
Set a review date tied to product changes and market launches. Regional search documentation can evolve quickly.
Conclusion
Regional search optimization fails when teams compare outputs without first comparing the experiences that produced them. Feature availability, eligibility, localized intent, source pools, competitors, and entity data can all create a market gap before content quality enters the diagnosis.
Build a dated feature map, localize prompts around decisions, benchmark the entities that actually appear, and audit the facts that feed each market. Combine answer-level monitoring with Search Console, analytics, and commerce systems, then prioritize changes by fixability and business value. Global consistency should protect the brand’s identity. Local evidence should make that identity useful in the market where the decision occurs.
FAQ
What is regional search optimization?
It is the process of adapting search measurement and execution to the features, languages, intent, competitors, sources, and data requirements of each market.
Why does AI search visibility differ by country?
Feature availability, language, local source pools, competitors, business data, eligibility, and user intent can all differ. A content gap is only one possible cause.
Should AI search prompts be translated directly?
Usually not. Preserve the decision intent, then rewrite the prompt with local terms, constraints, currencies, categories, and evidence expectations.
How do you compare AI visibility across markets?
Use the same intent framework and observation protocol, then segment by country, language, feature, prompt, competitor set, and source pool before aggregating.